
👋 About Me
Hi, I’m Jingbin Hu (胡景斌), a graduate student and researcher with the Audio, Speech and Language Processing Group (ASLP@NPU) at Northwestern Polytechnical University, Xi’an, China, advised by Prof. Lei Xie.
My research interests include audio generation, representation learning, and post-training. I work on expressive and controllable speech generation, speech and multimodal large language models, and audio representations. I enjoy building open research systems alongside developing new methods.
You can find my complete and up-to-date publication profile on Google Scholar and my code on GitHub.
⭐ Selected Contributions
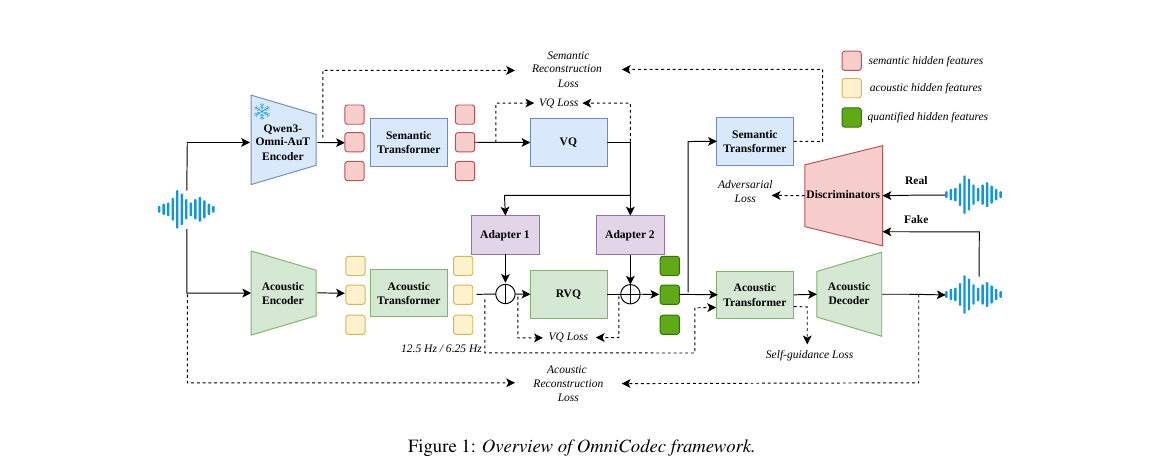
OmniCodec: Low Frame Rate Universal Audio Codec with Semantic-Acoustic DisentanglementFirst author
- Introduces a low-frame-rate universal codec for speech, music, and general audio.
- Separates semantic and acoustic information with a hierarchical multi-codebook design.
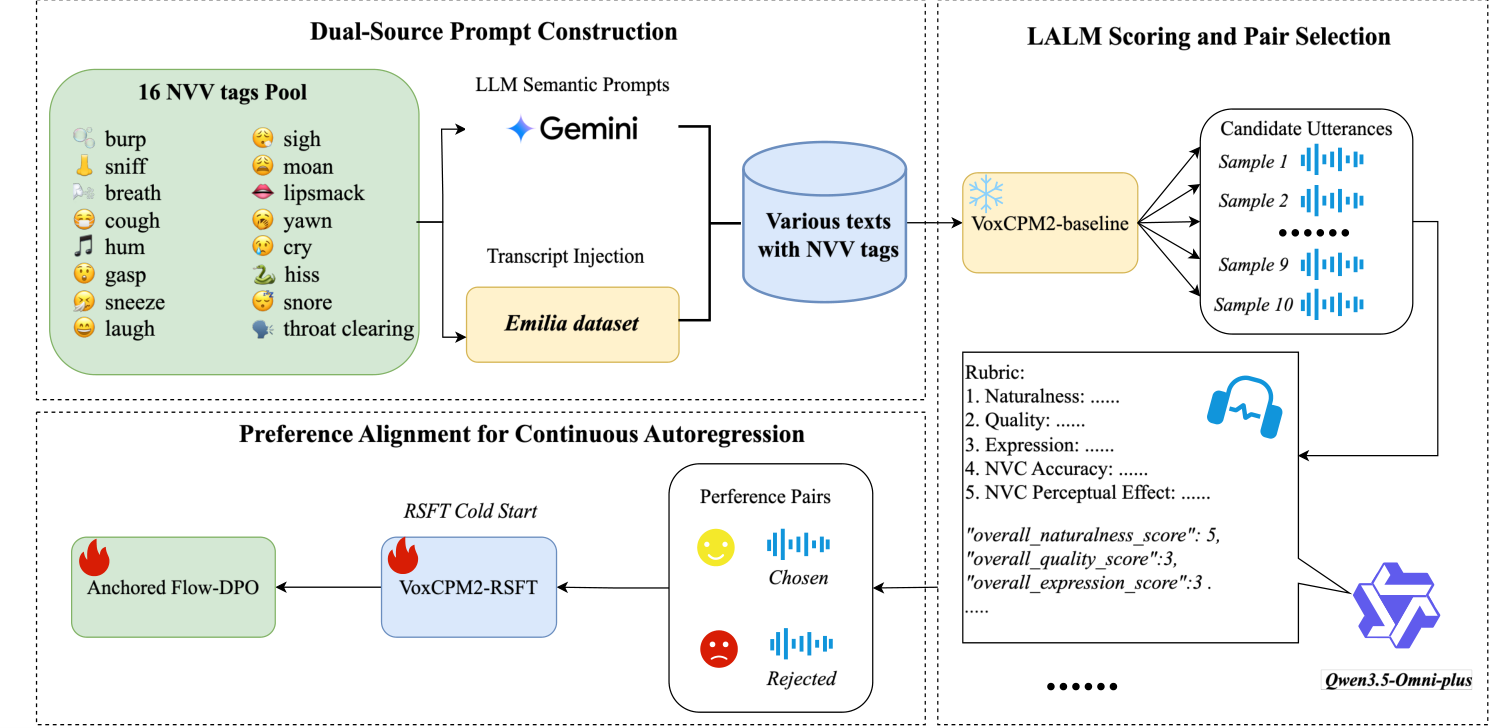
Preference Optimization with LALM Feedback for Continuous Autoregressive Non-Verbal Vocalization GenerationFirst author
- Uses large audio-language model feedback to build preference pairs for non-verbal vocalization generation.
- Combines rejection-sampling fine-tuning with Anchored Flow-DPO; achieves a 75.80 Track 2 score.
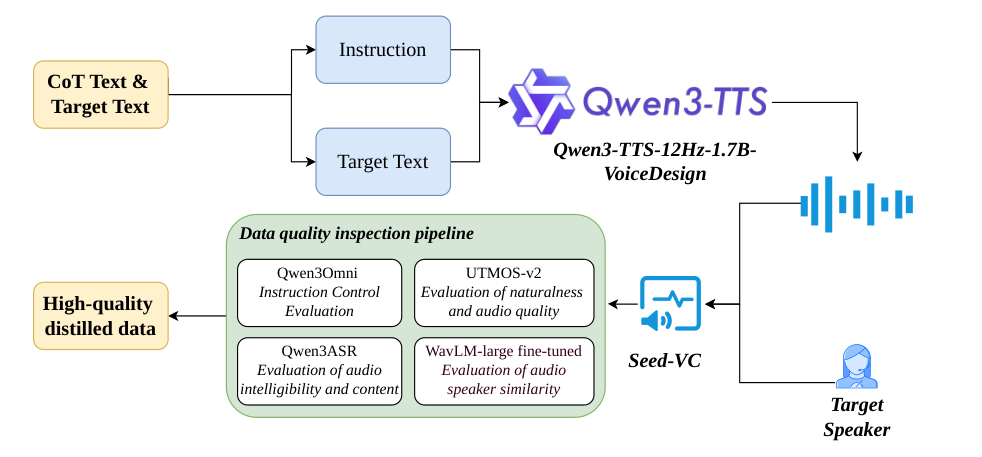
Bridging Data, Reasoning, and Alignment: A Unified Framework for Context-Aware Instruction-Following TTSFirst author
- Builds a data cleaning and distillation pipeline for context-aware, instruction-following speech synthesis.
- Introduces Context-Aware DPO to align dialogue history, reasoning, instructions, and generated speech.
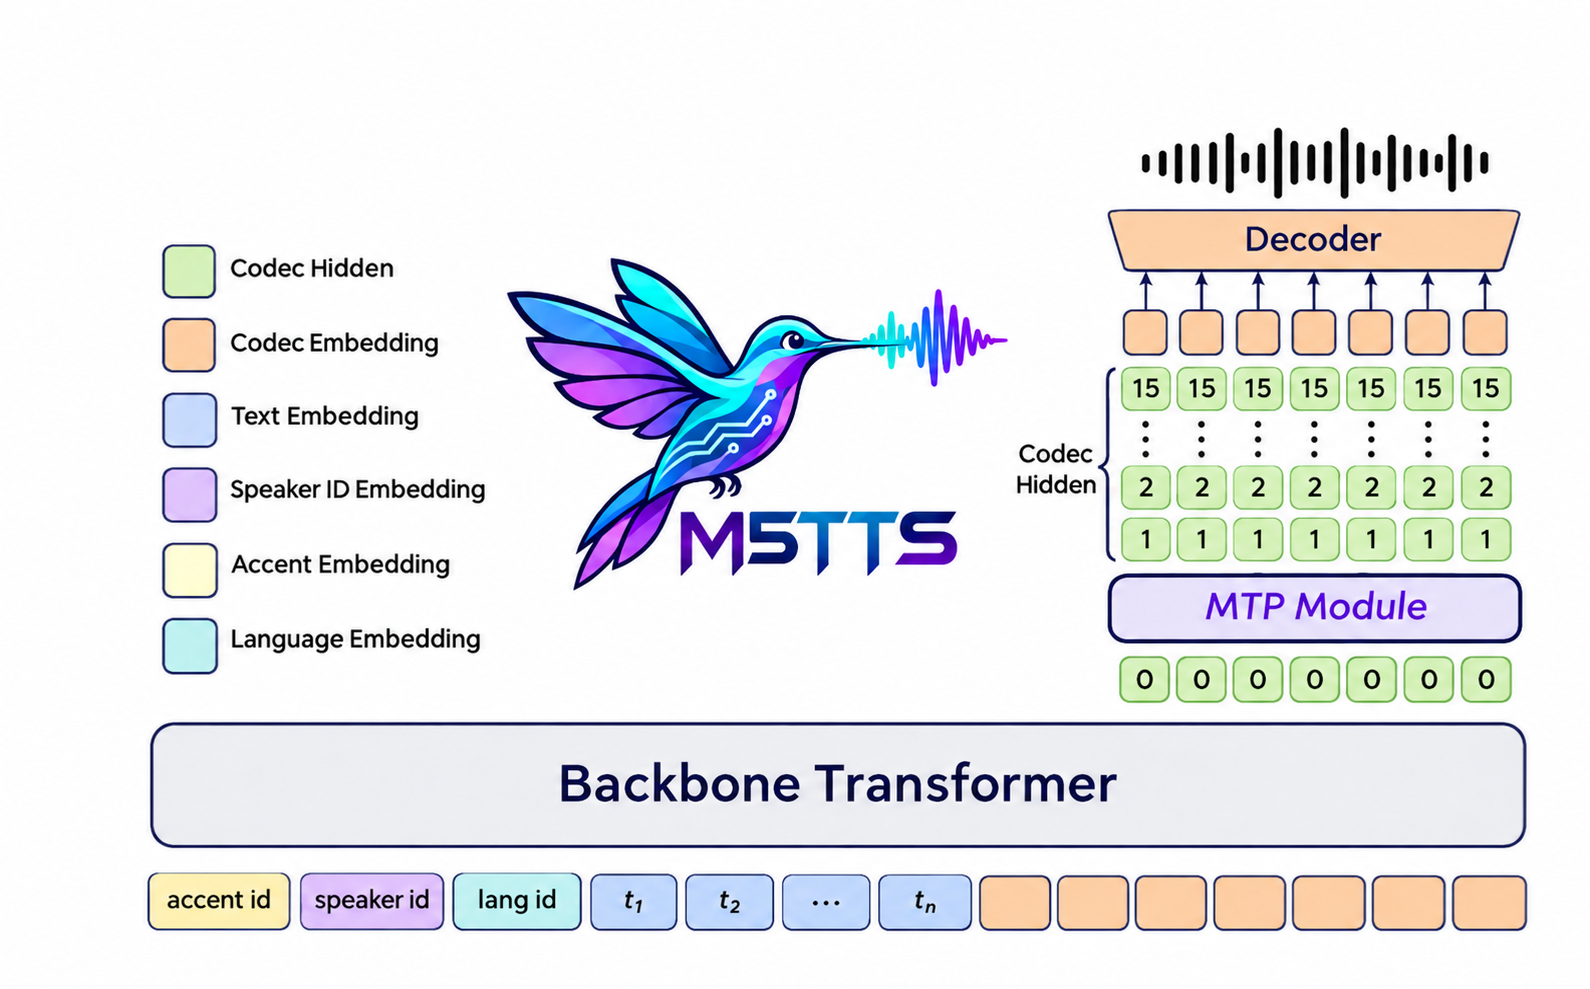
M5-TTS: A Mini-Scale Multilingual and Multi-Dialect Text-to-Speech Language Model with Multi-Token PredictionCo-first author
- Presents a compact 50M-parameter TTS language model for multilingual and Chinese multi-dialect speech.
- Uses multi-token prediction across 16 codec codebooks and supports zero-shot voice cloning and streaming.
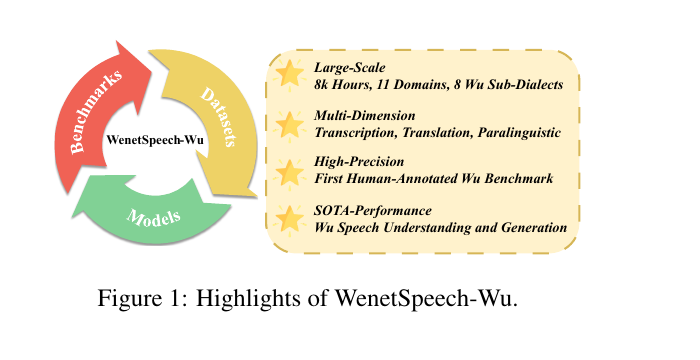
WenetSpeech-Wu: Datasets, Benchmarks, and Models for a Unified Chinese Wu Dialect Speech Processing EcosystemCo-first author
- Introduces an approximately 8,000-hour open Wu dialect corpus with multidimensional annotations.
- Pairs the corpus with a benchmark and open models across speech understanding and generation tasks.
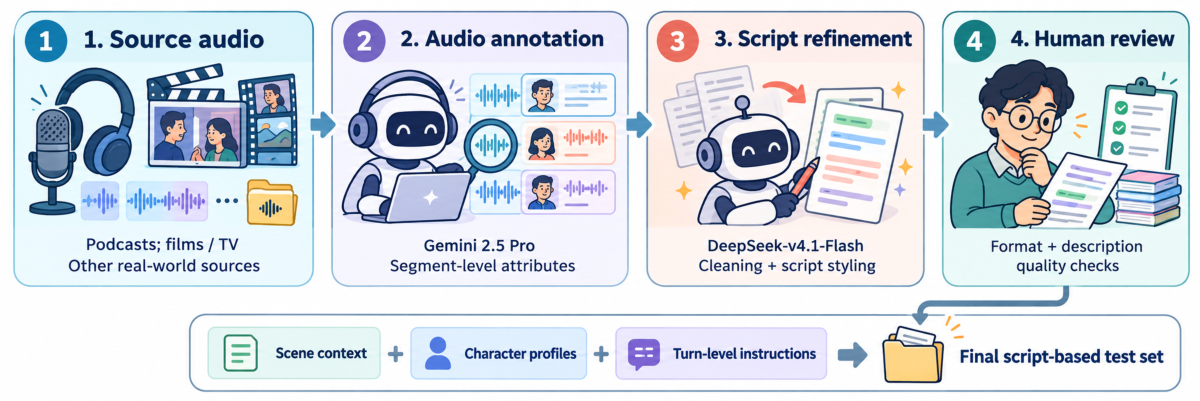
DRAMA-Eval: A Benchmark for Context-Aware, Multi-Turn, Multi-Speaker Speech GenerationFirst author
- Provides a 12-hour bilingual benchmark built from human-verified scripts and reference audio.
- Evaluates acoustic fidelity, local instruction execution, and long-range dialogue coherence.
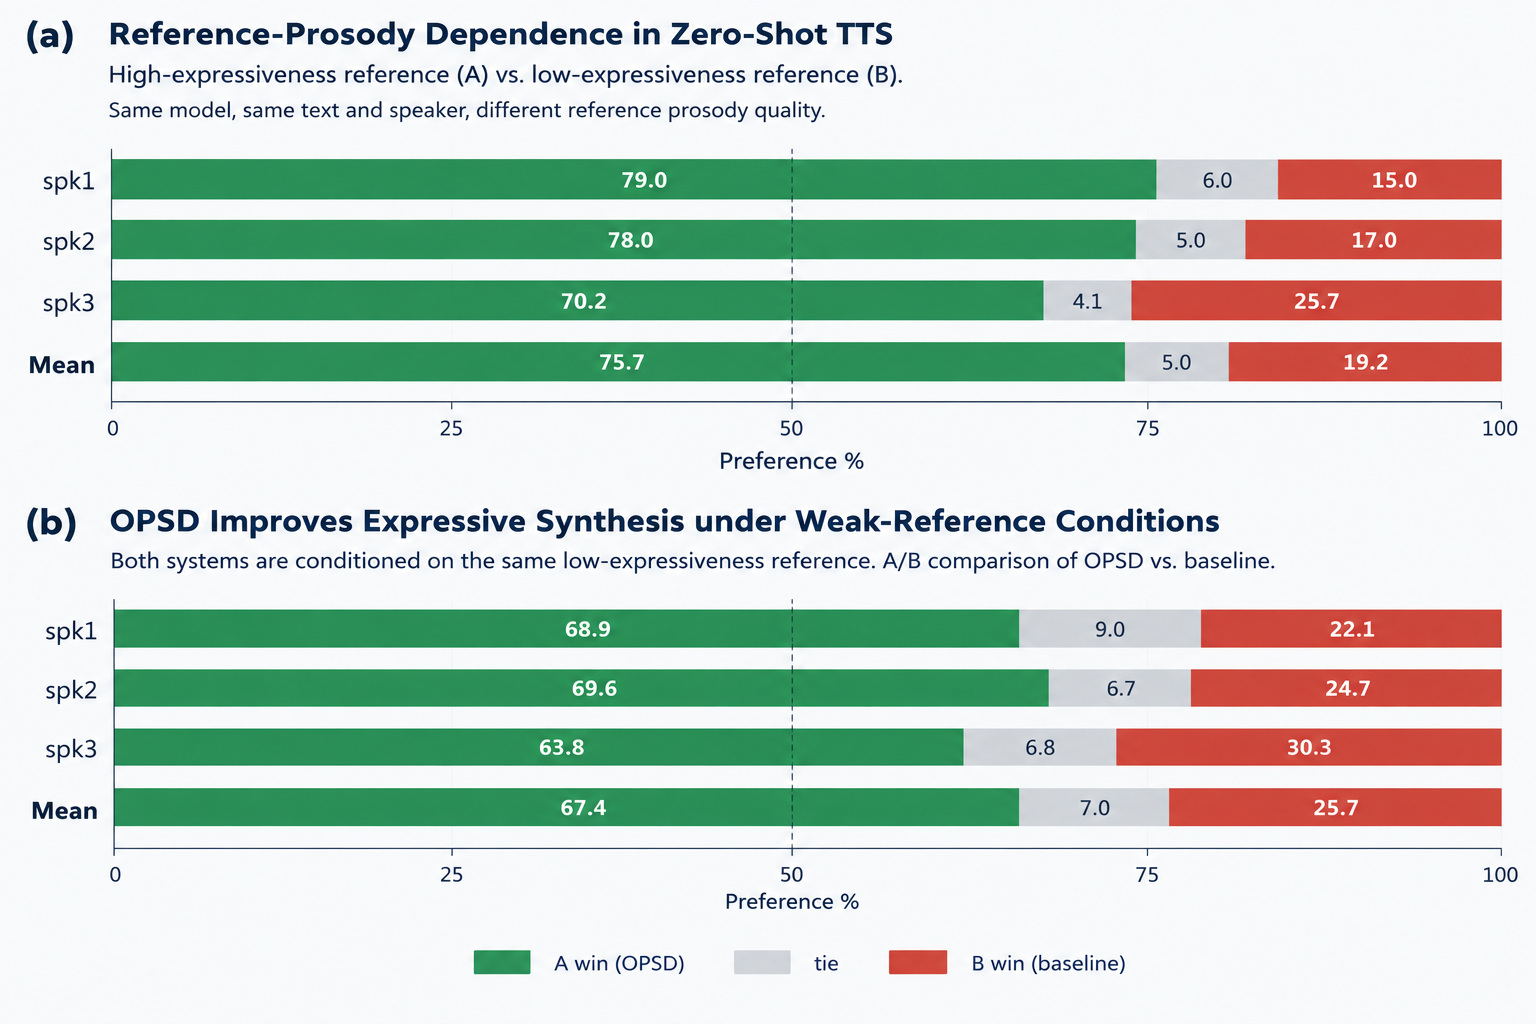
Rethinking Post-Training for Expressive Zero-Shot Text-to-SpeechFirst author
- Studies text-adaptive prosody for zero-shot voice cloning through a three-stage post-training framework.
- Combines DPO, GSPO, and context-conditioned on-policy self-distillation for expressive synthesis.
💻 Selected Research Projects
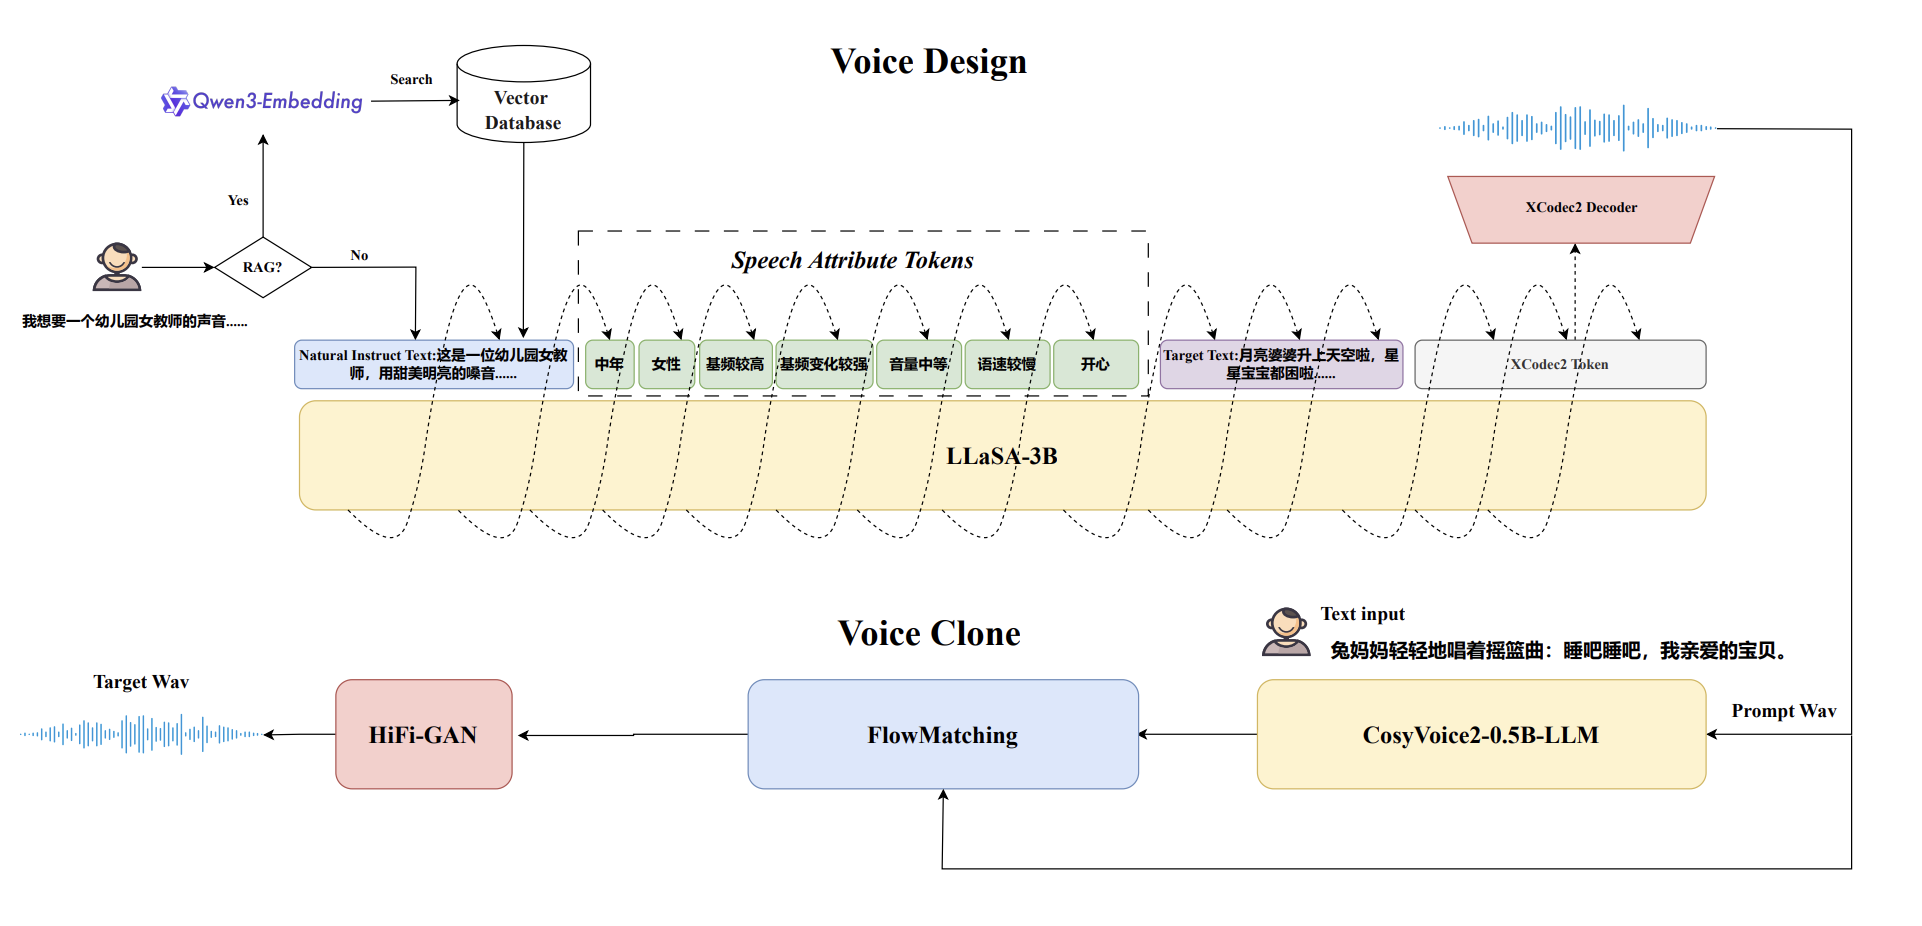
- VoiceSculptor — Instruction-based voice design and high-fidelity voice cloning, developed with ASLP Lab and collaborators.
- WenetSpeech-Wu — A large-scale Wu dialect speech corpus with multidimensional annotations, benchmarks, and models.
- M5-TTS — A compact multilingual and multi-dialect TTS language model designed for efficient inference and voice cloning.
- DRAMA-Eval — A bilingual benchmark for context-aware, multi-turn, multi-speaker speech generation.
- OmniCodec — A low-frame-rate universal audio codec with semantic–acoustic disentanglement.
Industry Collaborations
- Huawei Intelligent Automotive Solution Business Unit — Developed on-device text-to-speech for natural, expressive in-car voices, with control over phrasing and pauses.
- Huawei Central Media Technology Institute — Worked on speech synthesis for audio dramas, using natural-language instructions to direct how each character delivers a line.
- iQIYI — Developed expressive Thai dubbing using cross-lingual emotion transfer from a reference performance.
- Shanghai Lingguang Zhaxian Technology — Worked on voice design for film, TV, and animation, and co-developed OmniCodec, a low frame rate codec for speech, music, and environmental sounds.
- Shenzhen Pimei Technology Co., Ltd. — Led work on expressive dubbing for film and TV and co-developed DRAMA-Eval to assess how well generated dialogue follows a script across speakers and turns.
💼 Internships
- Audio Algorithm Intern, MiMo Team, Xiaomi · Nov 2026 – Present
- Speech Synthesis Algorithm Intern, Qwen Omni Team, Alibaba Group · Apr 2026 – Nov 2026
- Speech Synthesis Algorithm Intern, Yinwang Intelligent Technology Co., Ltd. · Huawei Auto BU · Jul 2025 – Oct 2025
📝 Publications
First- and Co-first-Author Papers
- VoiceSculptor: Your Voice, Designed By You · arXiv 2026
- OmniCodec: Low Frame Rate Universal Audio Codec with Semantic-Acoustic Disentanglement · Interspeech 2026 · Oral
- Preference Optimization with LALM Feedback for Continuous Autoregressive Non-Verbal Vocalization Generation · ISCSLP 2026 NVVSpeech Challenge, Track 2
- Bridging Data, Reasoning, and Alignment: A Unified Framework for Context-Aware Instruction-Following TTS · ISCSLP 2026 CoT-TTS Challenge · 1st Place
- M5-TTS: A Mini-Scale Multilingual and Multi-Dialect Text-to-Speech Language Model with Multi-Token Prediction · arXiv 2026 · co-first author
- WenetSpeech-Wu: Datasets, Benchmarks, and Models for a Unified Chinese Wu Dialect Speech Processing Ecosystem · Findings of ACL 2026 · co-first author
- DRAMA-Eval: A Benchmark for Context-Aware, Multi-Turn, Multi-Speaker Speech Generation · arXiv 2026
- Rethinking Post-Training for Expressive Zero-Shot Text-to-Speech · arXiv 2026
Co-authored Papers and Contributions
- FleSpeech: Flexibly Controllable Speech Generation with Various Prompts · arXiv 2025
- Qwen3.8-Omni: Towards Native Omni-Modal Agents · Qwen Team · team contribution
- FastTurn: Unifying Acoustic and Streaming Semantic Cues for Low-Latency and Robust Turn Detection · arXiv 2026
- MINT-Bench: A Comprehensive Multilingual Benchmark for Instruction-Following Text-to-Speech · ACM Multimedia 2026
- NVV-SuperBench: Beyond Words, Beyond Quality—Benchmarking Nonverbal Vocalizations in Speech Generation · Interspeech 2026
- EmoOmni: Bridging Emotional Understanding and Expression in Omni-Modal LLMs · arXiv 2026
- The NVVSpeech Challenge 2026: Overview and Lessons for Speech Understanding and Generation with Nonverbal Vocalizations · arXiv 2026
- MSVAE: Rethinking Musical Semantics in Continuous Latent Spaces · arXiv 2026
- WenetSpeech-Min: A Large-Scale Minnan Speech Corpus with Dual Transcriptions for Dialectal Speech Processing · arXiv 2026
- From Script to Drama: An Agentic Framework for Controllable Multi-Speaker Dialogue TTS · arXiv 2026
- Interactive TTS: Dynamic Speaking Style Adaptation for Expressive Speech Synthesis · arXiv 2026
- StreamTN: A Low-Latency Streaming Chinese Text Normalization Model for Streaming TTS in Dialogue Systems · arXiv 2026
- Rethinking Music Tokenization: A Semantic Codec toward High-Fidelity LLM Music Generation · arXiv 2026
- X-Pred MeanFlow for Streaming Token-to-Mel Speech Decoding · ISCSLP 2026
- SphereVAE: Hyperspherical Latent Autoencoders for Robust Autoregressive Speech Representation Modeling · arXiv 2026
- SpeechAnnotator: A Context-Aware Multi-Agent Framework and Benchmark for Multidimensional Speech Annotation · arXiv 2026
- SemBridge: Semantic Token Anchoring for Continuous-Latent Autoregressive Speech Generation · arXiv 2026
- FlashTTS: Fast Streaming TTS with MTP Acceleration and X-pred Mean Flow Distillation · Interspeech 2026
- MeanVC 2: Robust Low-Latency Streaming Zero-Shot Voice Conversion · Interspeech 2026
- Beyond Semantic Dominance: Cognitive Affective Reasoning and Empathetic Response Alignment in Audio Language Models · Interspeech 2026
- Towards Unified Song Generation and Singing Voice Conversion with Accompaniment Co-Generation · arXiv 2026
- Seeing the Context: Rich Visual Context-Aware Speech Recognition via Multimodal Reasoning · SLT 2026
- Towards Fine-Grained Multi-Dimensional Speech Understanding: Data Pipeline, Benchmark, and Model · arXiv 2026
- UrduSpeech: A 156-Hour Urdu Speech Corpus with 12-Dimension Paralinguistic Annotations · arXiv 2026
- Source-Adaptive Data Curation for Bilingual NVV-Aware ASR · ISCSLP 2026
- HiStyle: Hierarchical Style Embedding Predictor for Text-Prompt-Guided Controllable Speech Synthesis · arXiv 2025
- XEmoRAG: Cross-Lingual Emotion Transfer with Controllable Intensity Using Retrieval-Augmented Generation · IEEE ASRU 2025
📖 Education
- 2025.09 – 2028.06 · Graduate study, Northwestern Polytechnical University, Xi’an, China.
- 2021.09 – 2025.06 · Undergraduate study, Northwestern Polytechnical University, Xi’an, China.
For collaboration or research inquiries, email jingbin.hu@mail.nwpu.edu.cn.
🏆 Honors and Awards
- 1st Place, ISCSLP 2026 CoT-TTS Challenge — Bridging Data, Reasoning, and Alignment
- National Scholarship, China · awarded twice
- M Award, Mathematical Contest in Modeling / Interdisciplinary Contest in Modeling (MCM/ICM) · Top 15%
- First Prize, Shaanxi Provincial Division, National College Students Mathematics Competition